Parallel Computing Strategies for Casting Simulation
A deep dive into the computational architectures, domain decomposition strategies, and modern parallelization methods that are transforming the speed and fidelity of industrial casting simulation — from legacy sequential solvers to cloud-scale high performance computing.
The Computational Bottleneck
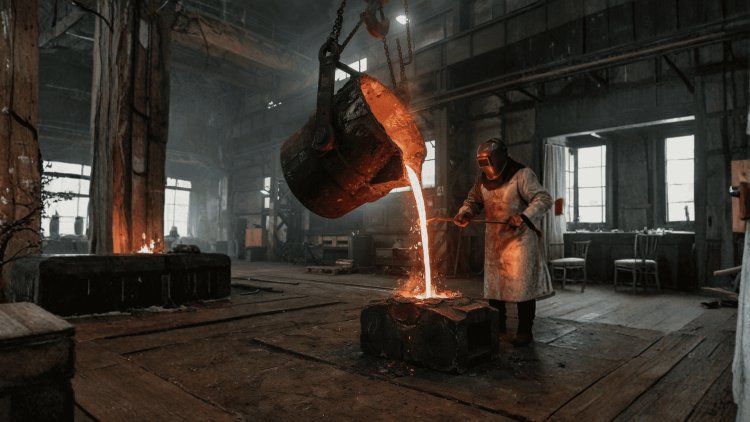
Casting simulation has evolved into one of the most computationally demanding disciplines in manufacturing engineering. As mesh sizes grow into the millions of elements and physics models become increasingly intertwined, traditional single-core processing approaches struggle to deliver results within practical engineering timelines. The challenge is no longer understanding the physics. The challenge is computing that physics fast enough to support modern product development.
Why Computational Throughput Matters
Legacy Sequential Processing
Traditional casting software solved problems sequentially on a single processor core. Every equation, matrix operation, and timestep was handled one after another. Regardless of hardware improvements, this architecture imposed a hard limit on simulation speed because only a single computational path could be executed at any moment.
Traditional Single-Core Workflow
FEM & FDM Computational Demands
Finite Element Methods (FEM) and Finite Difference Methods (FDM) require the simultaneous solution of enormous systems of coupled equations. Every timestep links temperature, velocity, phase fraction, stress, and shrinkage behavior together, creating computational systems that grow exponentially with mesh density and simulation complexity.
Of Floating-Point Operations
Transient casting simulations spanning hundreds of timesteps routinely require billions of mathematical operations, quickly exceeding what a single processor core can compute efficiently.
Complex Geometry & Transient Analysis
Examples of Computationally Intensive Components
Why These Models Are So Expensive
Parallel computing in casting simulation rests on three interlocking principles: how work is divided, how it is coordinated, and how communication overhead is minimized.
The simulation mesh is split into spatially coherent subdomains, each assigned to a processor. Neighboring partitions exchange boundary conditions at each time step.
A master node manages the global equation system—assembling matrices, enforcing global boundary conditions, and coordinating convergence checks.
Inter-processor communication is unavoidable. The Message Passing Interface (MPI) enables non-blocking operations so computation can continue while data transfers proceed asynchronously.
Foundations of
ParallelizationPartition the mesh, balance the load.
Central coordination, distributed work.
Hide latency, keep cores busy.
Minimize idle time, maximize useful work.
It is intelligent division, coordination, and overlap of work.
Shared Memory Parallel (SMP) architectures expose all processor cores to a unified memory pool, eliminating message-passing overhead. Commercial solvers like ProCast scale strongly up to ~16 threads, after which performance plateaus due to memory bus saturation. Profiling memory access patterns and matching thread count to physical cores is essential for efficiency.
These strategies consistently yield 10–20% performance improvements and prevent bandwidth saturation, enabling efficient use of modern multi-core workstations.
Modern Multi-Core Efficiency
The SMP Performance Curve
Practical Optimization Strategies
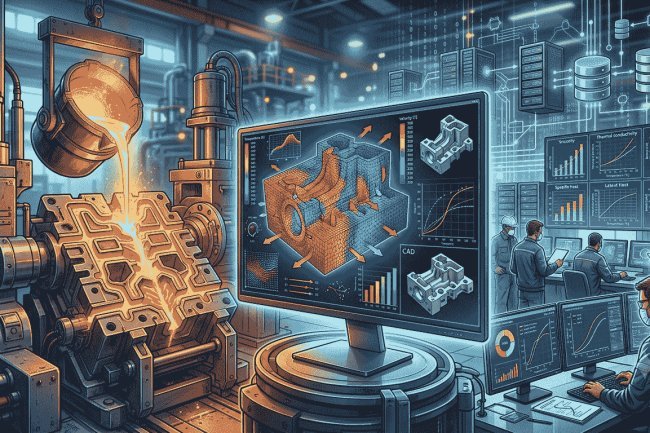
Modern casting simulation no longer depends solely on faster processors. Instead, performance gains come from sophisticated parallel architectures that distribute computational workloads across dozens, hundreds, or even thousands of processing cores. By combining distributed memory systems, shared memory processing, cloud-scale resources, and dynamic workload management, today's casting CAE environments can solve industrial-scale problems at speeds that were unimaginable only a decade ago.
Distributed Memory Parallel architectures assign each processing node its own dedicated memory resources. Nodes communicate through explicit message passing, typically using MPI frameworks, allowing extremely large simulations to be distributed across hundreds or thousands of processor cores.
DMP is essential when simulation memory requirements exceed what a single workstation can provide.
Shared Memory systems allow all processor cores to access the same memory address space. Because explicit message passing is not required, development complexity is reduced and parallelization can often be achieved through threading technologies such as OpenMP.
Most modern industrial solvers combine MPI communication between nodes with OpenMP threading inside each node, exploiting both distributed and shared memory advantages simultaneously.
Cloud platforms and national HPC grids such as PL-Grid provide simulation teams with temporary access to large computing environments. Engineers can scale resources on demand, execute large design studies, and avoid investing in permanently installed hardware infrastructure.
Cloud elasticity gives simulation teams the ability to launch large optimization campaigns without the financial burden of maintaining oversized local computing infrastructure.
Advanced Parallel Architectures
Four Pillars of Modern HPC Casting Simulation
Distributed Memory (DMP)
Key Characteristics of DMP
Intelligent Domain Decomposition
Shared Memory (SMP)
State-of-the-Art: Hybrid DMP + SMP
Cloud & HPC Grid Infrastructure
Compute Only When Needed
The next leap in casting simulation will come from algorithms and architecture—not just faster hardware—so fidelity and throughput can scale together.
High-quality mesh generation for complex castings can consume hours on a single thread. Parallel algorithms distribute geometry decomposition, element insertion, and quality optimization across multiple processors.
Coupled thermal–mechanical–electromagnetic FEM systems are challenging for direct and simple iterative solvers. Krylov subspace methods (GMRES, BiCGSTAB, CG) with physics-aware block preconditioners accelerate convergence.
The aspiration is simultaneous, fully coupled resolution of filling and solidification—capturing melt flow, thermal evolution, grain nucleation, dendrite growth, and macroscopic stress in a single framework from micrometers to meters.
Future Horizons:
Scaling Beyond the LimitRemove the pre-processing bottleneck.
Solve large, sparse, ill-conditioned systems faster.
One unified simulation across scales.
High-fidelity, fully coupled simulation as an engineering tool.
will make high-fidelity, fully coupled casting simulation routine—not exceptional.
What's Your Reaction?